[haproxy] The reload succeeded and the config still did not change
A reload can return rc=0 without applying anything. Two patterns: an old process surviving and serving the previous config, and changes landing in a staging file that never got promoted.
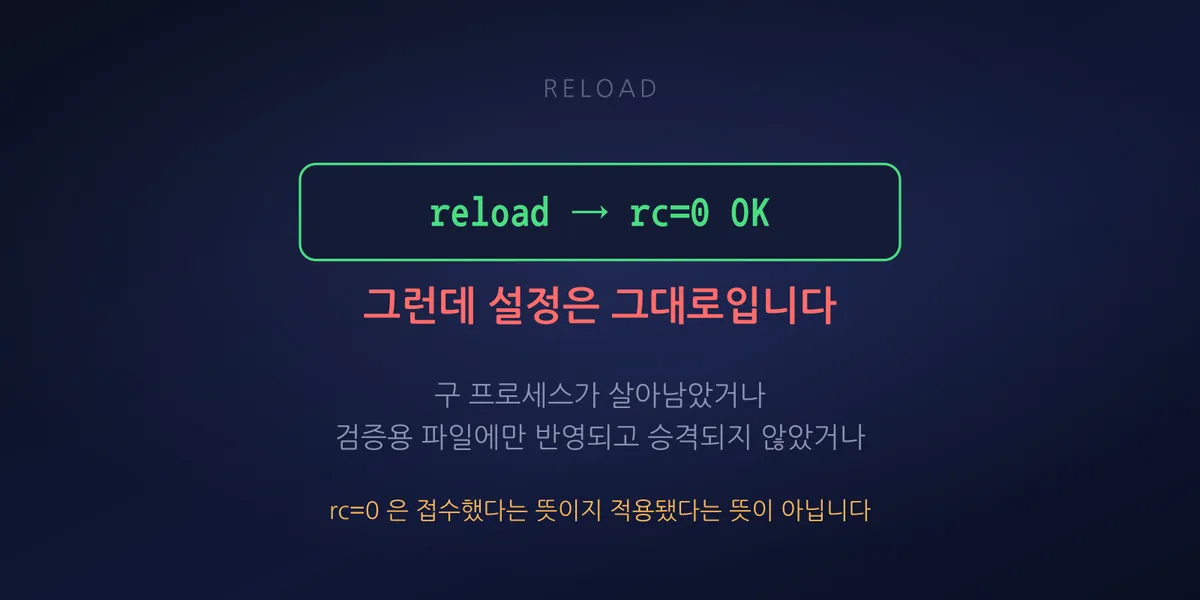
We edited the config and reloaded. The command printed OK and exited 0. From outside, the old
configuration was still in effect.
This happened twice, with different causes. Both illustrate that “the command succeeded” and “the configuration is live” are separate claims.
Case 1. The old process did not die
We ran reload and restart several times through the management tool and external responses still
showed the old config. The admin page reported every backend UP.
Counting processes gave it away.
pgrep -c haproxy
2
There were two where there should have been one. The new process had come up with the new config, and the old one was still holding the same port.
Linux SO_REUSEPORT makes this possible. With it, multiple processes can bind the same port
simultaneously. That is the mechanism behind zero-downtime restarts: the new process takes the
port, and the old one drains its in-flight connections and exits.
When it does not exit, the kernel distributes connections between both. Some requests get the new config, some get the old one. That is why the symptom is inconsistent — and why refreshing a few times can look like it fixed itself.
The fix is blunt. Kill it properly and start again.
service haproxy stop
pkill -9 haproxy      # clean up stragglers
service haproxy start
pgrep -c haproxy      # confirm 1
How to confirm it
Beyond the process count, we looked at two things.
A backend’s cumulative session counter (stot) shows which process is actually taking traffic.
If a backend that exists only in the new config stays at zero, that config is not serving anything.
Planting a marker is the definitive test. Add a response header in the config, request from outside, and see whether the header comes back. If it does, the new config is live. If not, the old process is answering.
Case 2. The change only reached the staging file
The second one was harder. We edited, reloaded, and again nothing applied — but this time there was only one process.
This management tool builds the config in two stages.
template render  ->  haproxy.conf.staging   (for validation)
reload           ->  haproxy.conf           (in use)
The problem was that reload returns rc=0 and OK even when the config has an error. The
staging file was written, validation rejected it, it was never promoted — and the command reported
success.
The underlying error was trivial: a directive that only works in a frontend had been placed in a backend.
error ... 'be_xxx' has no frontend capabilityThat message did not appear in the reload output. It appeared when we ran the config validation command separately. Watching only the reload, you never see it.
Along the way we suspected a caching problem and restarted the management daemon. Unrelated — a guess made without understanding the structure.
So what should you check after a reload
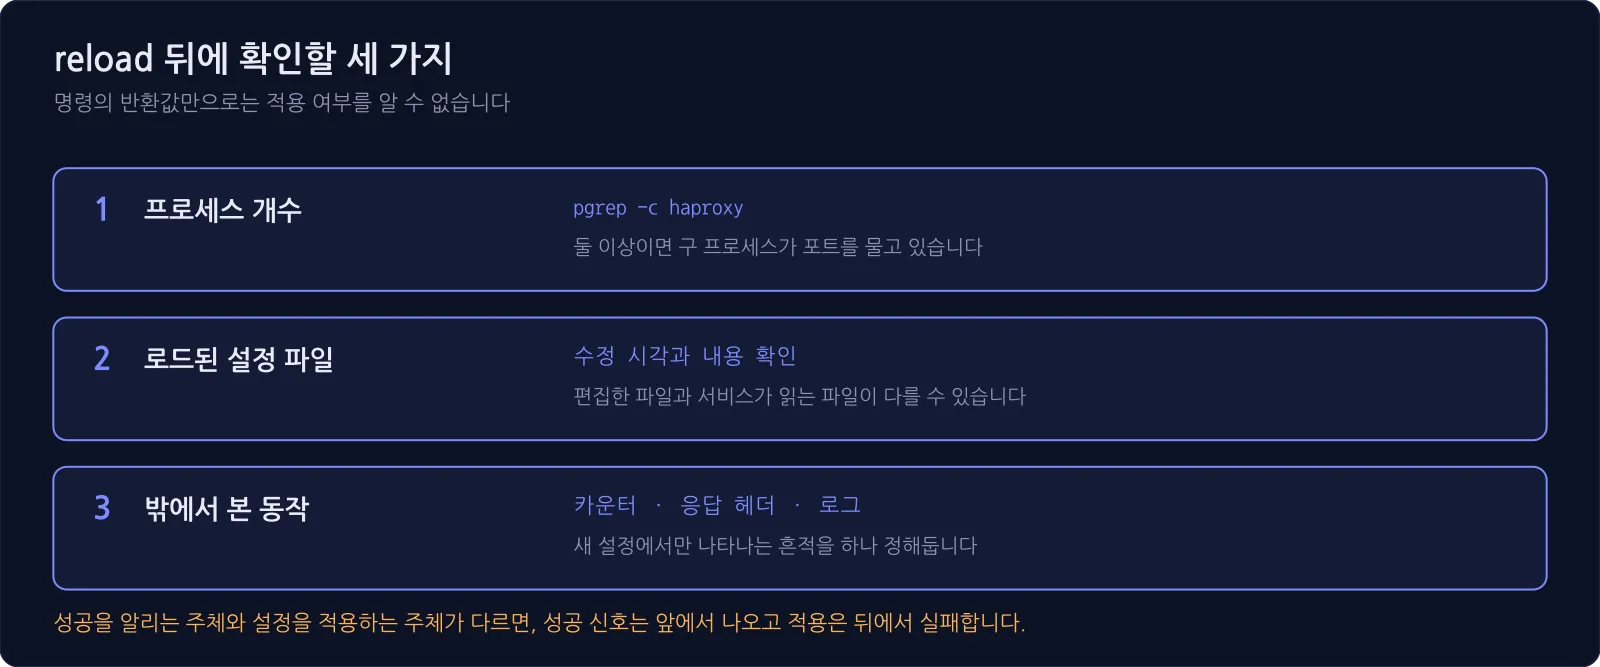
In neither case does the command’s return value tell you anything. Three things to verify after a reload:
One, how many processes are running. Anything doing zero-downtime restarts can leave the old one behind.
Two, which config file actually got loaded. The file you edited and the file the service reads can differ — staging structures, template generation, multiple include paths. Checking the file’s mtime and contents directly is faster than reasoning about it.
Three, whether behavior changed from outside. This is the only conclusive evidence. Pick one trace that only appears under the new config — a counter, a response header, a log line — and check for it.
This pattern is not specific to HAProxy
The same trap shows up elsewhere.
We once added a firewall rule, the command succeeded, and the saved ruleset did not contain it. The appliance’s management daemon was periodically rewriting the rules. On that device you have to use its own management tooling, not OS commands.
In redundant pairs, changes can land on only one side. Editing a config file directly means synchronization does not run, so the standby keeps the old config. Nothing goes wrong day to day — until a failover brings the old config back. That is the latest-discovered and most awkward variant.
The common thread: whatever reports success is not the thing that applies the config. Put a validation step, a sync step, or a rewriting daemon in between, and the success signal comes from the front while the failure happens at the back.
Summary
rc=0only guarantees the command was accepted- Count processes after a reload. Zero-downtime restart designs can leave the old one running
- Check that the file you edited is the file the service reads
- Pick one trace that only exists under the new config and verify it from outside
- In a redundant pair, check the partner node. Synchronization may not be automatic
The most dangerous moment in a config change is not when it fails. It is when it fails and reports success.